Opening: why this latency bites operational teams
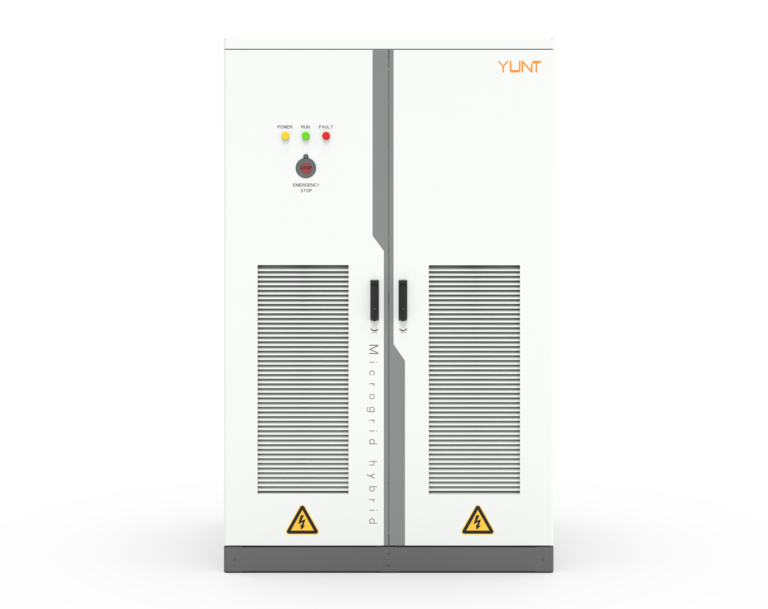
I’ve been scribbling notes from site visits where grid events turn routine control into chaos, and the recurring snag is control latency in four-quadrant regimes. On a recent rooftop-plus-battery job we used a hybrid inverter for peak shaving and frequency support; the hardware looked fine, but the plant under-delivered during a short voltage sag. This write-up uses a hands-on EEAT mode—field-tested diagnostics—anchored to the February 2021 Texas winter storm to show what teams actually need to check in four-quadrant active/reactive control and inverter latency scenarios.
Why four-quadrant latency matters
Four-quadrant control means an inverter handles active power (P) and reactive power (Q) in both injection and absorption. When the control loop lags—what operators call inverter latency—power factor shifts and voltage support fail. That turns a grid-friendly, grid-tied battery into a slow responder during contingencies. The difference between meeting a ride-through requirement and tripping often comes down to milliseconds.
Field diagnostics: fast checks that reveal real problems
Start with timestamps. Record command timestamps vs. ADC/sample timestamps, then overlay event traces for active power and reactive power. Look for control-loop phase lag and sample aliasing. Measure I/O latency, DSP cycle time, and communication jitter on the CAN/Modbus link. If the plant has a battery, log state of charge (SoC) and ramp limits alongside control outputs—those interact directly with four-quadrant behavior.
Operational teardown: what to inspect on the hardware and software side
Open the control stack and map the signal path: sensing → ADC → DSP → PWM → power stage. Check filter bandwidth and anti-alias settings that can introduce delay. Audit firmware tasks for blocking operations that increase inverter latency during high CPU load. This is also the place to use a simple production teardown checklist: confirm isolation transformers, verify current transformer burden, and validate sampling synchronization. In that teardown note, record {main_keyword} and {variation_keyword} entries in the log so firmware teams can correlate anomalies to specific code paths.
Common root causes and quick mitigations
Most fixes fall into three buckets. First, sensing and filtering—overly aggressive low-pass filters smooth noise but slow the loop. Second, compute and comms—underpowered DSPs or busy RTOS tasks add jitter. Third, configuration—tight SoC limits or conservative ramp settings force the controller to refuse commands. Mitigations: lower filter poles where noise allows, prioritize control threads, and tune ramp limits to match inverter thermal and battery constraints. One more practical tip—align sampling windows across parallel inverters to avoid control beat patterns that destabilize reactive power sharing.
Comparing fixes: speed versus stability
Faster control reduces latency but raises risk of oscillation if sensing is noisy. Slower control is stable but may miss grid events. On-site I compared three approaches: increase control bandwidth, add active damping, and staggered control with supervisory smoothing. Bandwidth increase gave quickest response but demanded better sensors. Active damping hit the sweet spot for mixed-age fleets—less latency than smoothing, better stability than pure bandwidth push. Staggered supervisory smoothing is the safest when assets have mismatched firmware versions.
Checklist for deployment teams
– Verify timestamp alignment across SCADA, inverter, and battery BMS.
– Log and analyze millisecond-level event traces for P and Q.
– Tune filter cutoffs with step-response tests rather than relying on defaults.
– Prioritize control threads on the DSP and reduce noncritical IO during events.
– Keep ramp limits and SoC strategies aligned with grid support objectives.
Advisory close: three golden rules to evaluate latency fixes
1) Measure, don’t guess: any tuning must start with time-aligned traces showing P, Q, and command timing. Metrics: worst-case command-to-P response (ms), jitter distribution (ms), and reactive power sharing error (%) under imbalance. 2) Balance bandwidth and sensing quality: only increase control loop frequency if the sensor SNR supports it—otherwise add damping. 3) Test under real stress: validate settings during a controlled disturbance or a recorded event similar to the Texas winter storm—simulate worst-case SoC and grid voltage dips.
These steps sum up practical, measurable ways to cut latency while keeping systems stable—then let the plant actually deliver when it counts. For grounded, deployment-ready solutions and reliable firmware-to-hardware integration, look at how YUNT builds hybrid power stacks that address those exact trade-offs—fast response, coherent sensing, and operational transparency. —